
Chatbot Training Guide
Structured Data V.S. Unstructured Data
Your AI agent learns from two kinds of training data, and they are stored differently:
- Structured data (Q&A pairs, CSV rows, imported products) is kept whole, and the AI agent prefers it when answering.
- Unstructured data (documents, web pages, plain text, transcripts) is split into small text chunks. It is hard to know exactly where to cut, so a fact can end up split across two chunks and some important information can be lost.
That is why structured data usually gives more accurate answers. Use it for the facts that matter most.
How your AI agent finds the right content
Chat Data answers with a method called Retrieval-Augmented Generation (RAG):
- A visitor asks a question.
- Chat Data searches your training data for the pieces that best match the question.
- It picks the most relevant pieces: text chunks, or whole Q&A pairs and products.
- The AI agent writes its answer from those pieces.
Challenges with Unstructured Data
Problems start at step 3 when a fact has been split. Take the sentence "Jack Freeman is a good friend of Jimmy". It might be cut into "Jack" and "Freeman is a good friend of Jimmy".
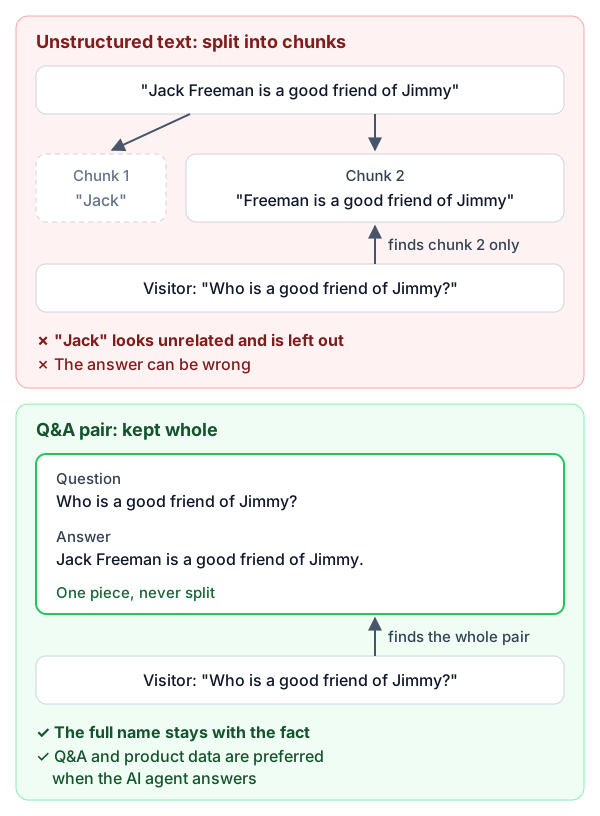
Asked "Who is a good friend of Jimmy?", the search finds the second chunk and skips "Jack" because it looks unrelated, so the answer can be wrong. Structured data doesn't have this problem, because it is never split mid-sentence.
Which data is which
| Kind | Source (tab in Sources) | What is used for training |
|---|---|---|
| Structured | .csv file | Each row becomes one record (see below) |
| Structured | Q&A | The question and answer pairs you enter |
| Structured | Product | Products imported from WooCommerce, Shopify, PrestaShop, Magento or Shopware |
| Unstructured | .pdf file | Plain text and tables |
| Unstructured | .docx file | Plain text |
| Unstructured | .html file | Plain text, tables and links |
| Unstructured | .txt file | Raw text |
| Unstructured | Website | Plain text, tables and links from each page |
| Unstructured | Text | The plain text you type in |
| Unstructured | Audio and video | Text transcribed from the audio |
.csv
A CSV file imports many structured records at once. The first row holds the column names; each following row becomes one record (a JSON object) with those names. For example, this CSV:
| user   | expected response |
|--------|-------------------|
| query1 | response1         |
| query2 | response2         |
becomes these records:
[
  {"user": "query1", "expected response": "response1"},
  {"user": "query2", "expected response": "response2"}
]
You can use as many columns as you need. Give each column a clear, meaningful name. Don't ask the AI agent to count rows: the file is processed row by row into separate records.
Next step: add your most important facts as Q&A pairs, or see Train With Your Data for every source type.
Frequently Asked Questions
Why does the page say structured data usually performs better for chatbot training?
Because structured data keeps relationships and boundaries intact, while unstructured data has to be split into text chunks for RAG retrieval, which can cause important information to be separated and weaken answer quality.
How does the RAG workflow affect unstructured data?
RAG retrieves relevant text chunks based on embeddings and cosine similarity. The problem is that chunking unstructured text can split related information apart, causing the chatbot to miss important context.
What upload types are considered structured data in Chat Data?
CSV files, user-entered Q&A pairs, and product data imported from WooCommerce, Shopify, PrestaShop, Magento or Shopware are structured data.
How are CSV files treated during training?
CSV files are converted row by row into JSON objects using the first row as the schema, which preserves the structured relationship between columns and values.